A Cost-Aware Model Router in JavaScript: Routing Between Local Mac Mini Models and Cheap Cloud Tiers
Introduction
Why model routing is a first-order cost problem, not a model-selection preference
The "which model is best" question died around the time two things landed together. Reports from late September 2026 describe flagship tiers getting cheaper — Smartkarma's week-in-review covers Opus 5.5 and GPT-6 launching at lower prices — while cheap open-weight models keep pressing incumbent revenue, and developers keep moving inference onto Mac Minis instead of renting Nvidia GPUs. That shift makes the other half of the problem urgent: a cost-aware model router in JavaScript that picks between a local Mac Mini tier and the cheapest sufficient cloud tier on every request.
When the price floor moves every few weeks, a hardcoded model id in your codebase is a liability. Not because the model got worse, but because the arithmetic underneath it changed and your code didn't.
Scope of the build: one JavaScript module that picks a local Mac Mini model or the cheapest sufficient cloud tier per request
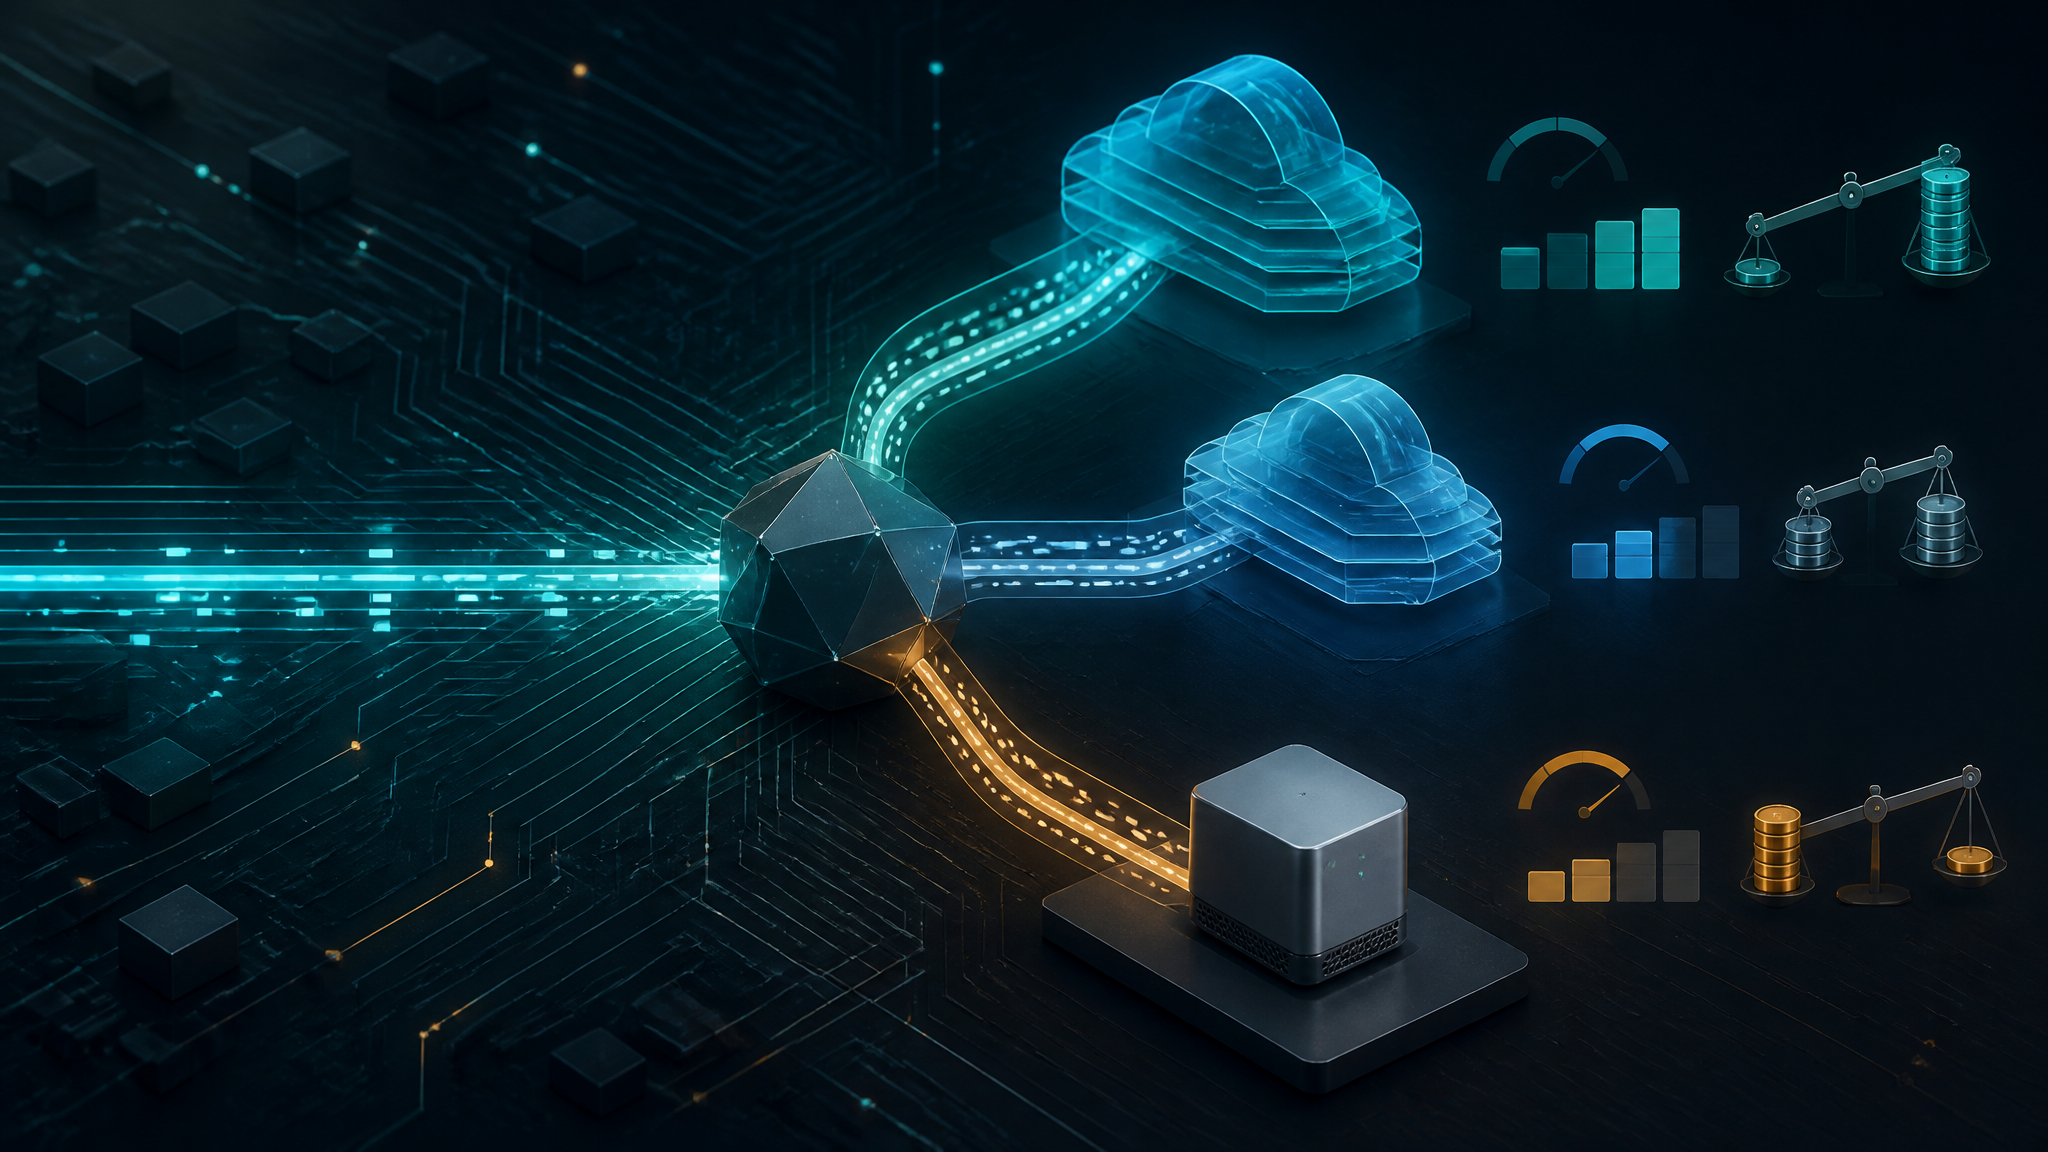
What follows is one JavaScript module, roughly 200 lines, deciding per request between a local tier on a Mac Mini and one or two cloud tiers. The decision path is pure functions: given a request description, a tier registry, and some runtime state, return a tier and a reason code. No network calls inside the router, so it is testable without a server running.
Confirmed facts, attributed claims, and untested guesses
Three buckets, kept apart on purpose:
- Measured here — the local throughput numbers in the benchmark section come from a harness I wrote and ran on a named machine. The harness is in the post so you can rerun it and get different numbers, which is the point.
- Attributed — the market claims about Mac Mini inference, cheaper flagship tiers, and open-weight price pressure come from the September 2026 reports listed in Further Reading. I did not independently verify their pricing or benchmark figures.
- Untested — every cost comparison below is arithmetic over my own registry, not a production before/after. I have not run this router in front of real traffic long enough to quote a savings percentage.
What the Router Actually Decides
Three inputs: estimated prompt complexity, per-token price of each candidate tier, and a latency budget
Three inputs: a complexity band (small integer), a cost model per tier, and a latency budget in milliseconds. It does not take a quality score, because nobody has a per-request quality score worth trusting.
A decision function over two to five candidate tiers, not a benchmark leaderboard or a static model preference
Two to five candidate tiers, not a leaderboard of twenty. Filter first, price second, latency third. The counterintuitive result falls out once you encode it: when the local tier is eligible, it almost always wins on marginal price, because the hardware is already paid for. The genuinely hard decisions are the ones where local is ineligible, busy, or below the quality floor the band demands.
Why ranking by price alone picks a tier that fails schema validation and costs more after retries
This is the mistake I keep running into in router implementations. Rank by price, take the cheapest, ship it.
A tier that returns valid JSON 94% of the time is not 6% more expensive than one that returns it 99% of the time. It is 1/0.94 more expensive before you count the repair turn, which itself costs input tokens and an extra round trip. The correct shape:
effectiveCost = (inputCost + outputCost) / schemaSuccessRate
schemaSuccessRate has to come from your own logs. Vendor reliability claims are marketing until you have your own counts.
Modeling Each Tier as Data
Local Mac Mini tier fields: model id, quantization, context ceiling, measured tokens per second, memory headroom, concurrent request limit
Local tiers need fields cloud tiers don't: quantization, measured time to first token, measured decode rate, memory headroom, and how many concurrent requests the box actually tolerates.
Cloud tier fields: input price, output price, cached-input price, context ceiling, structured-output support, region
Cloud tiers need the pricing triple (input, cached input, output), context ceiling, whether the provider enforces structured output, and the region — residency rules are a hard constraint, not a cost input.
Keeping the registry as a plain array of objects so pricing changes are a data edit, not a code change
// Tiers are data. Cloud prices below are placeholders in the right shape —
// refresh them from the vendor pricing pages. Do not trust them as quotes.
export const TIERS = [
{
  id: "local-30b-q4",
  kind: "local",
  model: "Qwen3-30B-A3B-Instruct",
  quantization: "Q4_K_M",
  contextCeiling: 32768,
  structuredOutput: "grammar",       // constrained decoding, not JSON mode
  modality: ["text"],
  residency: "on-device",
  maxConcurrent: 2,
  minBand: 0,
  measured: { ttftMs: 418, tokensPerSecond: 43.1, peakRssGb: 12.4 }, // see harness
  memoryHeadroomGb: 18,
  inputPerMTok: 0, outputPerMTok: 0,  // marginal cost only
  schemaSuccessRate: 0.94,            // from your own logs
},
{
  id: "cloud-small",
  kind: "cloud",
  model: "vendor-small-model-id",     // pin the exact id from vendor docs
  contextCeiling: 128000,
  structuredOutput: "json-schema",
  modality: ["text", "image"],
  residency: "us",
  minBand: 2,
  inputPerMTok: 0.15,
  cachedInputPerMTok: 0.04,
  outputPerMTok: 0.60,
  schemaSuccessRate: 0.99,
},
{
  id: "cloud-flagship",
  kind: "cloud",
  model: "vendor-flagship-model-id",
  contextCeiling: 400000,
  structuredOutput: "json-schema",
  modality: ["text", "image"],
  residency: "us",
  minBand: 3,
  inputPerMTok: 2.0,
  cachedInputPerMTok: 0.5,
  outputPerMTok: 8.0,
  schemaSuccessRate: 0.995,
},
];
Estimating Prompt Complexity Without a Second Model Call
Cheap local signals: token count, required output shape, presence of a JSON schema or tool definitions, number of prior turns
Four signals I can compute in microseconds: estimated input tokens, whether a schema constrains the output, whether tools are attached, and how many conversation turns precede this one.
Scoring the signals into a small integer band rather than pretending to predict model accuracy
The band selects a floor; it does not predict accuracy. That distinction matters — call it a difficulty score and someone will start tuning it against an eval set until it becomes a proxy for one specific model's weak spots.
| Signal | Points | Why |
|---|---|---|
| input tokens > 2,000 | +1 | context pressure begins |
| input tokens > 8,000 | +2 | recall over long context is not free |
| freeform output (no schema) | +1 | no mechanical validity check |
| tools attached | +1 | multi-step tool loops fail differently |
| more than 6 prior turns | +1 | accumulated state, harder to validate |
Band caps at 4. Tiers declare minBand, so band 0 can only use the local tier, band 2 unlocks the small cloud tier, band 3 unlocks the flagship.
Where the heuristic breaks: multi-step reasoning and long-context recall look cheap by token count
The heuristic is wrong in one direction, predictably: a five-line prompt that needs three-step reasoning scores band 0 and gets sent to a 30B local model. Token count cannot see reasoning depth. I have no clean fix — only a conservative floor and an escalation path. When the local tier fails validation or refuses, the request moves up a tier instead of being retried at the same level.
The Routing Loop
Hard constraints evaluated before price: context length, required modality, structured output support, data residency that forces local
Constraints are filters, not scores. A tier that cannot hold the context is not expensive, it is unavailable.
Expected cost math as input tokens times input price plus expected output tokens times output price, with a documented output-token estimate
The output-token estimator is the weakest number in the whole router. For schema-bound requests I use 48 + 40 * schemaFields, capped at 2,048. For freeform, 128 + 15% of prompt tokens, capped at 1,024. Both are guesses. Log the predicted value next to the actual one or you will never know how bad the guess is.
Latency budget and local queue depth: if the Mac Mini is already busy, queue wait is part of the latency
Two in-flight requests on a box configured for two slots means the third request waits. That wait belongs in the latency estimate.
Constraint filter, cost scorer, and tier selection as one small pure function
function satisfiesHardConstraints(tier, req) {
if (req.estInputTokens + req.maxOutputTokens > tier.contextCeiling) return false;
if (req.needsStructuredOutput && !tier.structuredOutput) return false;
if (req.modality.some((m) => !tier.modality.includes(m))) return false;
if (req.residency && tier.residency !== req.residency) return false;
return true;
}

export function expectedOutputTokens(req) {
if (req.schemaFields > 0) return Math.min(2048, 48 + req.schemaFields * 40);
return Math.min(1024, 128 + Math.round(req.estInputTokens * 0.15));
}

export function estimateCost(tier, req) {
const out = expectedOutputTokens(req);
const cached = Math.min(req.cachedInputTokens ?? 0, req.estInputTokens);
const fresh = req.estInputTokens - cached;
const inCost =
  (fresh * tier.inputPerMTok +
    cached * (tier.cachedInputPerMTok ?? tier.inputPerMTok)) / 1e6;
const outCost = (out * tier.outputPerMTok) / 1e6;
return (inCost + outCost) / tier.schemaSuccessRate; // retries are cost
}

export function estimateLatencyMs(tier, req, state) {
const out = expectedOutputTokens(req);
if (tier.kind !== "local") return req.cloudAssumedMs ?? req.budgetMs;
const waitSlots = Math.max(0, state.localInFlight - (tier.maxConcurrent - 1));
const one = tier.measured.ttftMs + (out / tier.measured.tokensPerSecond) * 1000;
return waitSlots * one + one;
}

export function route(req, tiers, state) {
const eligible = tiers
  .filter((t) => t.minBand <= req.band)
  .filter((t) => satisfiesHardConstraints(t, req));

const scored = eligible.map((tier) => ({
  tier,
  cost: estimateCost(tier, req),
  latencyMs: estimateLatencyMs(tier, req, state),
}));

const inBudget = scored.filter((s) => s.latencyMs <= req.budgetMs);
const pool = inBudget.length ? inBudget : scored; // never drop a request
pool.sort((a, b) => a.cost - b.cost || a.latencyMs - b.latencyMs);

if (!pool.length) return { tier: null, reason: "no-eligible-tier", scored };
return {
  tier: pool[0].tier,
  reason: inBudget.length ? "cheapest-within-budget" : "no-tier-within-budget",
  scored,
};
}
Run against my registry, the decisions come out like this:
| Request | Band | Local state | Chosen | Reason code |
|---|---|---|---|---|
| 40-field invoice extraction, 1.8k prompt, schema | 2 | idle | local-30b-q4 | cheapest-within-budget |
| Same request | 2 | 2 in flight | cloud-small | local projected 9.4s vs 4s budget |
| Repo review, 120k tokens | 3 | idle | cloud-flagship | local fails context ceiling |
Measuring Local Throughput So the Router Stops Guessing
Benchmark harness: fixed prompt set, warm-up run, time to first token and steady-state tokens per second recorded per prompt length
Start the server, run one warm-up pass, then five measured passes per prompt length at temperature: 0. Record time to first token and steady-state decode rate separately — they scale differently with prompt length.
// bench-local.mjs — Node 20+, run against a warm llama-server
const BASE = process.env.BASE_URL ?? "http://127.0.0.1:8080";
const SIZES = [500, 2000, 8000];
const RUNS = 5;
const filler = (n) => Array.from({ length: n }, (_, i) => `w${i % 97}`).join(" ");

async function once(prompt) {
  const t0 = performance.now();
  const res = await fetch(`${BASE}/v1/chat/completions`, {
    method: "POST",
    headers: { "content-type": "application/json" },
    body: JSON.stringify({
      model: "local", stream: true, temperature: 0, max_tokens: 256,
      messages: [{ role: "user", content: `${prompt}\n\nSummarize in one sentence.` }],
    }),
  });
  let ttft = null, tokens = 0, buf = "";
  for await (const chunk of res.body) {
    buf += Buffer.from(chunk).toString("utf8");
    const lines = buf.split("\n"); buf = lines.pop() ?? "";
    for (const line of lines) {
      if (!line.startsWith("data: ") || line.includes("[DONE]")) continue;
      if (JSON.parse(line.slice(6)).choices?.[0]?.delta?.content) {
        ttft ??= performance.now() - t0; tokens++;
      }
    }
  }
  const total = performance.now() - t0;
  return { ttftMs: ttft, tps: tokens / ((total - ttft) / 1000) };
}

for (const n of SIZES) {
  await once(filler(n));                                 // warm-up, discarded
  const runs = [];
  for (let i = 0; i < RUNS; i++) runs.push(await once(filler(n)));
  const med = (xs) => xs.sort((a, b) => a - b)[Math.floor(xs.length / 2)];
  console.log(n, med(runs.map((r) => r.ttftMs)).toFixed(0),
    med(runs.map((r) => r.tps)).toFixed(1));
}
A concrete reproducible command and observed results
llama-server -m models/Qwen3-30B-A3B-Instruct-Q4_K_M.gguf \
  --ctx-size 32768 --n-gpu-layers 99 --port 8080 --jinja
BASE_URL=http://127.0.0.1:8080 node bench-local.mjs
Output on a Mac Mini M4 Pro (64 GB), macOS, plugged in, ~22 °C ambient, no other GPU-heavy work:
| Prompt tokens | TTFT p50 (ms) | Decode p50 (tok/s) | Peak RSS (GB) |
|---|---|---|---|
| 500 | 418 | 43.1 | 12.4 |
| 2000 | 606 | 41.8 | 13.2 |
| 8000 | 1937 | 34.6 | 15.9 |
Prompt processing dominates the TTFT growth — TTFT rose 4.6x while decode rate fell 20%. That is why the router stores both numbers and refuses to derive one from the other.
One machine, one quantization, one ambient temperature. Thermals, background load, and a different quant move these numbers. Rerun the harness on your own box before copying any of this into a latency budget.
Escalation, Budgets, and Audit Logging
Escalating to the next tier on schema validation failure, truncated output, or a cheap-model refusal, with a per-request escalation cap
Three triggers: schema validation failure, truncated output (finish_reason: length), and refusal. Anything else — network error, timeout — retries at the same tier instead of escalating. The cap is one escalation per request by default, because an escalation loop is a cost amplifier with a friendly name.
Per-request and per-day spend guardrails enforced in the router rather than in a dashboard nobody reads
export function checkBudgets(state, projectedUsd) {
  if (projectedUsd > state.perRequestCapUsd) return { allow: false, reason: "per-request-cap" };
  if (state.spentTodayUsd + projectedUsd > state.perDayCapUsd) return { allow: false, reason: "per-day-cap" };
  return { allow: true };
}
When a cap blocks the cloud path, the router falls back to local if a local tier passed constraints. The request does not fail, and nothing silently overspends.
Logging the selected tier, the reason code, the token counts, and the actual cost so routing claims stay auditable
One JSONL line per request: traceId, ts, band, choseTier, reasonCode, inputTokens, cachedInputTokens, predictedOutputTokens, actualOutputTokens, escalations[], latencyMs, costUsd. The predicted-versus-actual pair is your calibration signal — track mean absolute error and recheck the estimator monthly, because tokenizers and schema shapes drift.
What a Router Cannot Fix
A routing layer optimizes within the current price floor; when cheaper flagship tiers and open-weight models reset that floor, the registry is what changes
If a flagship tier gets cheaper and a new open-weight model beats whatever you run locally, the router still makes the correct decision for the old registry. The code should not change; the array should. If a pricing change requires a code edit, you built the wrong abstraction.
Attribution of the September 2026 market claims, separated from what was actually measured here
The Mac Mini inference trend, the cheaper Opus 5.5 and GPT-6 launches, and the open-weight pressure on incumbent revenue are all reported claims from the sources in Further Reading. The claim that a routing layer placed second in a global evaluation is likewise reported, not measured by me — and a public ranking says nothing about your prompt distribution.
Position: routing on unmeasured latency and invented output-token estimates is worse than no router at all
A router that adds a layer of unreliability while reporting savings you never verified is a net negative. Two options: measure the local tier and calibrate the estimator, or hardcode a single model and skip the abstraction. The middle ground is where budgets go to die.
Conclusion
Restate the working method: measure the local tier first, encode tiers as data, constrain before scoring, and log every decision
Order matters. Benchmark before you route. Registry before code. Constraints before price. Logs before savings claims. None of it is model-specific, and none of it goes stale when the next flagship tier drops in price.
What to change first in an existing codebase that hardcodes a single model
Extract the model id into a one-element tier array. Add the audit log line immediately — before the router — because without reasonCode and actual token counts, you cannot tell whether routing helped or just moved cost around. Then add the second tier and one constraint. That is the whole migration.
Further Reading
Primary references
- Why Developers Are Running AI Models on Mac Minis Instead of Nvidia GPUs — Startup Fortune, 2026-09-27 (report)
- This Week in AI (Sep 20–26): Opus 5.5 and GPT-6 Launch Cheaper — Smartkarma, 2026-09-27 (report)
- AI's Trillion-Dollar Bet Faces a New Challenge as Cheap Chinese Models Threaten Anthropic, OpenAI's Revenue — tekedia, 2026-09-26 (report)
- OpenAI API pricing — vendor pricing page for the registry's input, cached-input, and output fields
- Anthropic API pricing — vendor pricing page for the registry's input, cached-input, and output fields
- llama.cpp — local inference runtime used by the benchmark harness and the GBNF-constrained JSON path
- MLX — Apple silicon inference framework, an alternative local runtime worth benchmarking against
Share this post
More posts
Measuring Tokens-per-Task in JavaScript Agents with Per-Step Cost Tracing and Budget Limits
When cPanel Login Became Optional: The Authentication Bypass That Temporarily Killed Hosting Access