Auditing Model Routing and Prompt Caching Before You Trust the Cost Chart
A hands-on audit framework for verifying that an LLM gateway's model routing and prompt caching actually cut token spend before you trust the vendor's cost chart.

A hands-on audit framework for verifying that an LLM gateway's model routing and prompt caching actually cut token spend before you trust the vendor's cost chart.

How Claude Haiku 5.5's dramatic price cut to $0.10/$0.50 per million tokens forces a re-evaluation of model routing thresholds and RAG fan-out strategies for cost-sensitive LLM applications.

A practical walkthrough of how the 47% quarterly decline in AI inference prices reported by EpochAI reshapes marginal cost modeling, batching, caching, and model routing decisions for subscription-based AI coding agents.

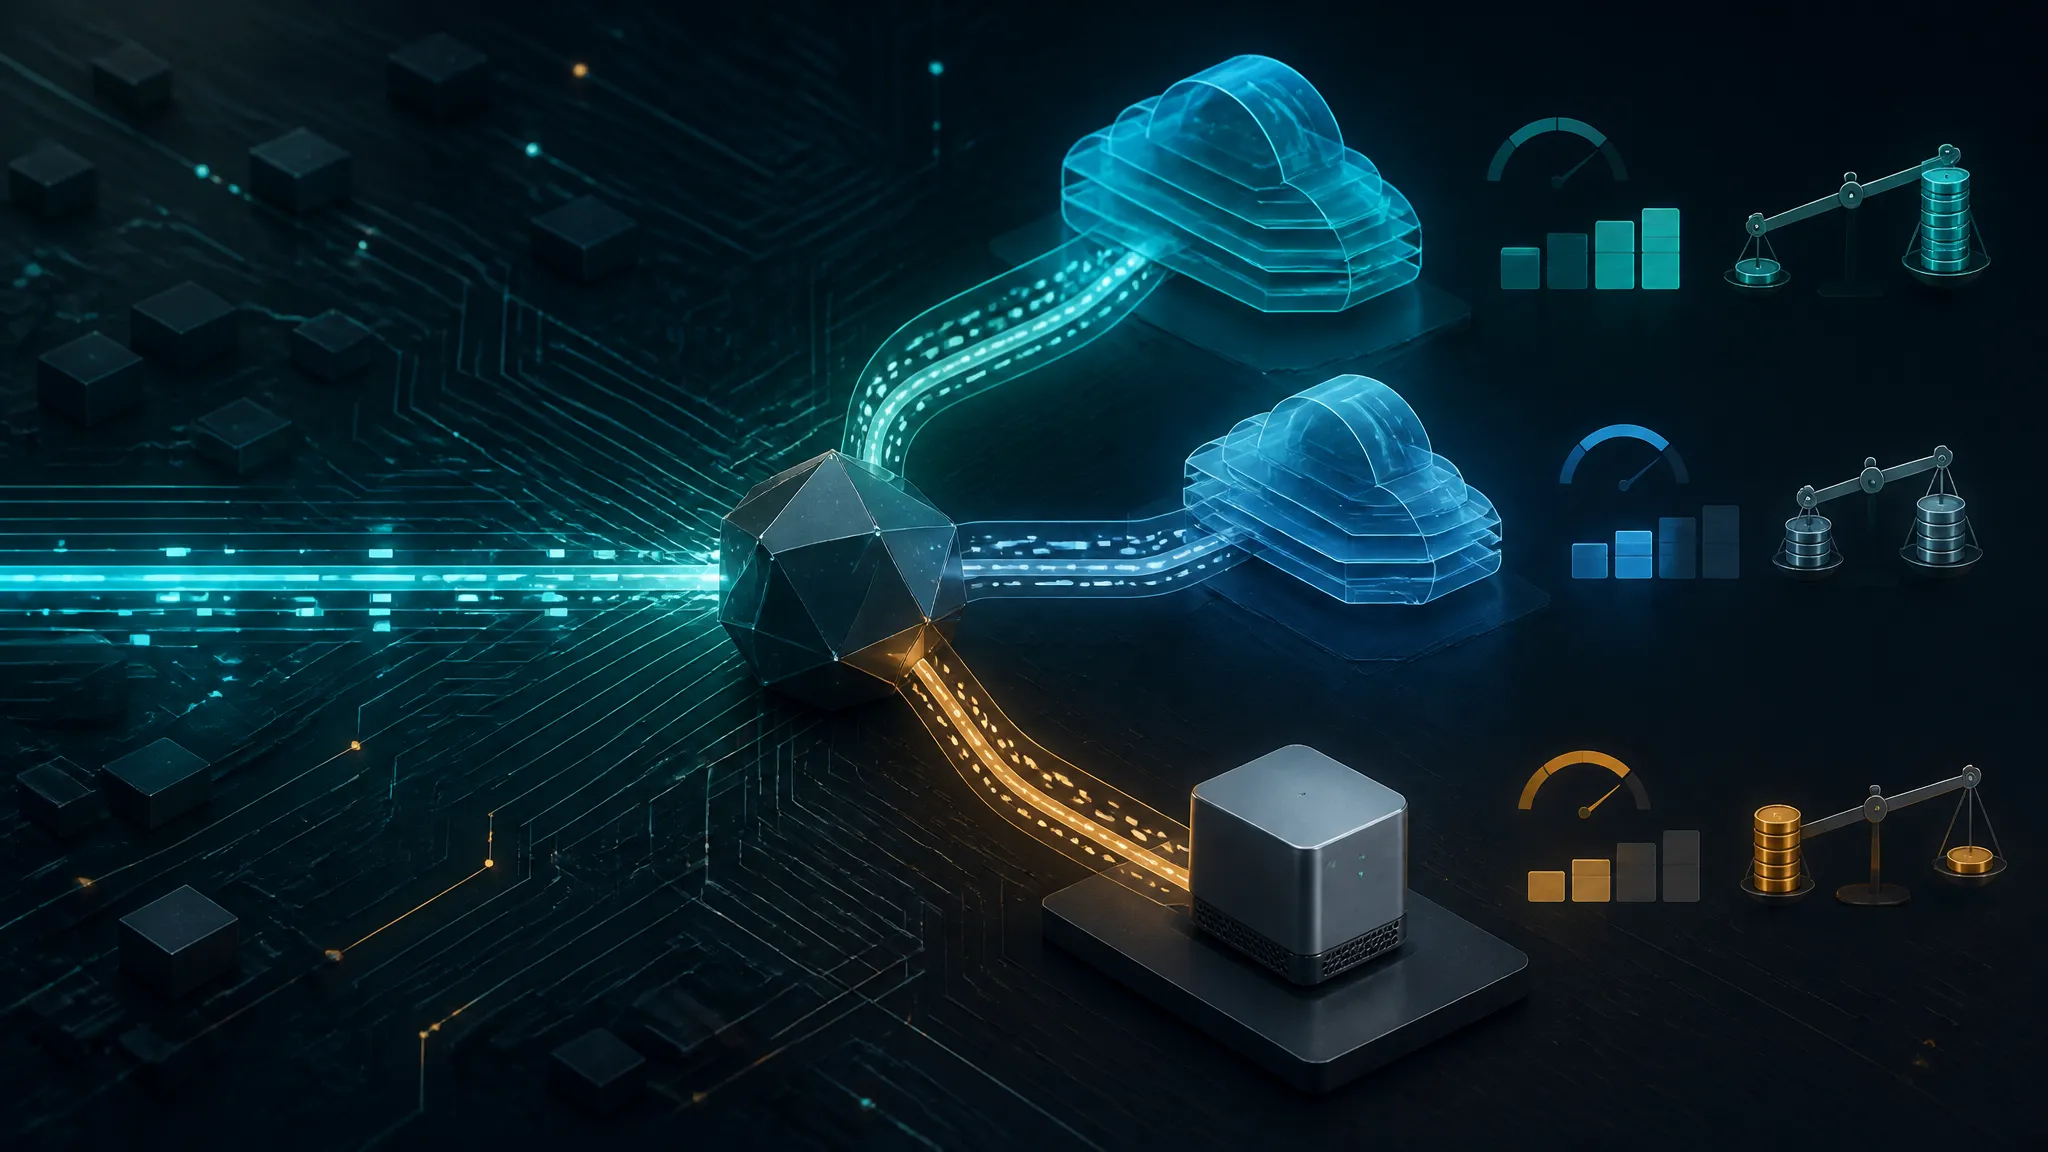
Build a cost-aware JavaScript router that sends each LLM request to a local Mac Mini model or the cheapest sufficient cloud tier based on prompt complexity, per-token price, and latency budget.

A deep technical walkthrough of how to design resilient AI model fallback architectures, using Anthropic’s Fable 5 and Mythos 5 access restrictions as a case study for safe routing, provider redundancy, and failover controls.