Why Single-Provider AI Clients Break Under Load and How to Route Around Them
On 15 October 2026, three reports landed within hours of each other: DeepSeek refunded users after its second outage in three days, Yandex restored most of its AI services after an outage, and Russia's tax service suffered a widespread disruption that the reporting ties to drone attacks on major data centers. This post uses those incidents to answer one engineering question: why single-provider AI clients break under load, and how to route around provider failures with fallback ordering, jittered retries, deadline-aware queueing, and degradation tiers you can actually ship. The headlines carry almost no detail, so I'll be careful about what they do and don't establish — the design conclusion doesn't depend on those details anyway. Each incident says the same thing: if your AI client has one base URL, your product's uptime is someone else's incident response.
The Default AI Client Is a Single Point of Failure
The default integration is one SDK, one API key, one base URL, and one retry policy inherited from whatever the library shipped. That's a wrapper, not an architecture. It holds until the provider starts returning 503s — and then every layer above it, your retries, your queue, your UX, either absorbs the shock or magnifies it.
My position: treat model providers the way you treat availability zones. Not as interchangeable commodities, but as failure domains you route around on purpose.
What the October 2026 AI Outages Actually Show
DeepSeek's Second Disruption in Three Days
The report, published 15 October 2026 and surfaced via Weibo, says DeepSeek refunded users after a second outage inside three days. Confirmed by the report: a second disruption in a three-day window, and refunds issued. Not in the report: what failed, how long degradation lasted, which endpoints were hit, the size or form of the refund, or whether it was automatic. "Second in three days" also implies an earlier incident I have no source for.
Yandex Partial Restoration and the Wider Data-Center Signal
A separate report dated 15 October 2026 says most Yandex AI services were restored after an outage. Most is the operative word — it describes a degraded state where some endpoints answer and others don't. That's exactly the state your router has to survive, because a naive health check sees a working API. Separately, The New Voice of Ukraine reported that Russia's tax service suffered a widespread outage following reported drone attacks on major data centers. The drone attribution is what the report claims; I have not independently verified a causal link.
What the Reports Do Not Say
None of the three establish root cause, error-budget impact, status-page timelines, SLA credit terms, affected regions, or whether the incidents relate. Two are aggregator headlines with a single sentence of context. If you see a confident "it was a GPU shortage" or "it was a network partition" takeaway elsewhere, that's inference, not reporting.
Why Single-Provider Clients Buckle Under Load
Retries Amplify Congestion Instead of Relieving It
Most SDKs retry by default. Multiply that across your fleet:
attempts = replicas × in-flight per replica × (1 initial + retries)
         = 20 × 25 × 4
         = 2000 attempts
A provider having a bad minute now eats 2,000 requests from you alone inside one backoff window. That doesn't relieve congestion, it extends it. Use exponential backoff with full jitter and a retry budget your whole fleet shares rather than one each process owns.
const delay = Math.random() * Math.min(30_000, 500 * 2 ** attempt);
Retrying a streaming request that already produced tokens can double your bill and duplicate side effects if the call triggered tools. Only retry the whole request when you know nothing was consumed.
Coupled Failure Domains: Auth, Quota, Streaming, and Status
Provider health is not a boolean. These fail independently and need separate handling:
| Signal | Meaning | Same provider retry? | Route elsewhere? |
|---|---|---|---|
| 401/403 | Auth or config error | No | No — fixing one key fixes all |
429 + Retry-After | Throttled | Yes, honour the header | Only if header exceeds your deadline |
| 500/502/503 | Capacity or gateway | Yes, jittered | Yes, once the circuit opens |
| Stream ends without terminator | Truncated response | Once, whole request | Yes |
| Timeout after first token | Slow, possibly healthy | No | Yes |
| 200 with invalid JSON schema | Contract violation | No | Yes, for JSON-mode routes |
Streaming Makes Partial Failure Invisible to the Caller
This is the least-tested failure mode in production AI clients. A stream that dies after 400 tokens still returned HTTP 200. A client that only checks the status code writes a truncated answer to your database and never notices. You have to look at the terminator explicitly:
export async function consume(stream, { expectTerminator = true } = {}) {
const reader = stream.getReader();
const decoder = new TextDecoder();
let bytes = 0;
let sawTerminator = false;

while (true) {
  const { value, done } = await reader.read();
  if (done) break;
  bytes += value.byteLength;
  const chunk = decoder.decode(value, { stream: true });
  if (chunk.includes("data: [DONE]")) sawTerminator = true;
}

if (expectTerminator && !sawTerminator) {
  const err = new Error("stream ended without terminator");
  err.code = "STREAM_TRUNCATED";
  err.bytesReceived = bytes;
  throw err;
}
}
One edge case worth knowing: not every provider sends data: [DONE], and some close with a usage frame instead. Make the terminator configurable per provider. If you set expectTerminator: false, detect truncation another way — finish reason, usage frame, or schema validation of the assembled payload. Otherwise you've switched off the only check you had.
Build a Router, Not a Wrapper
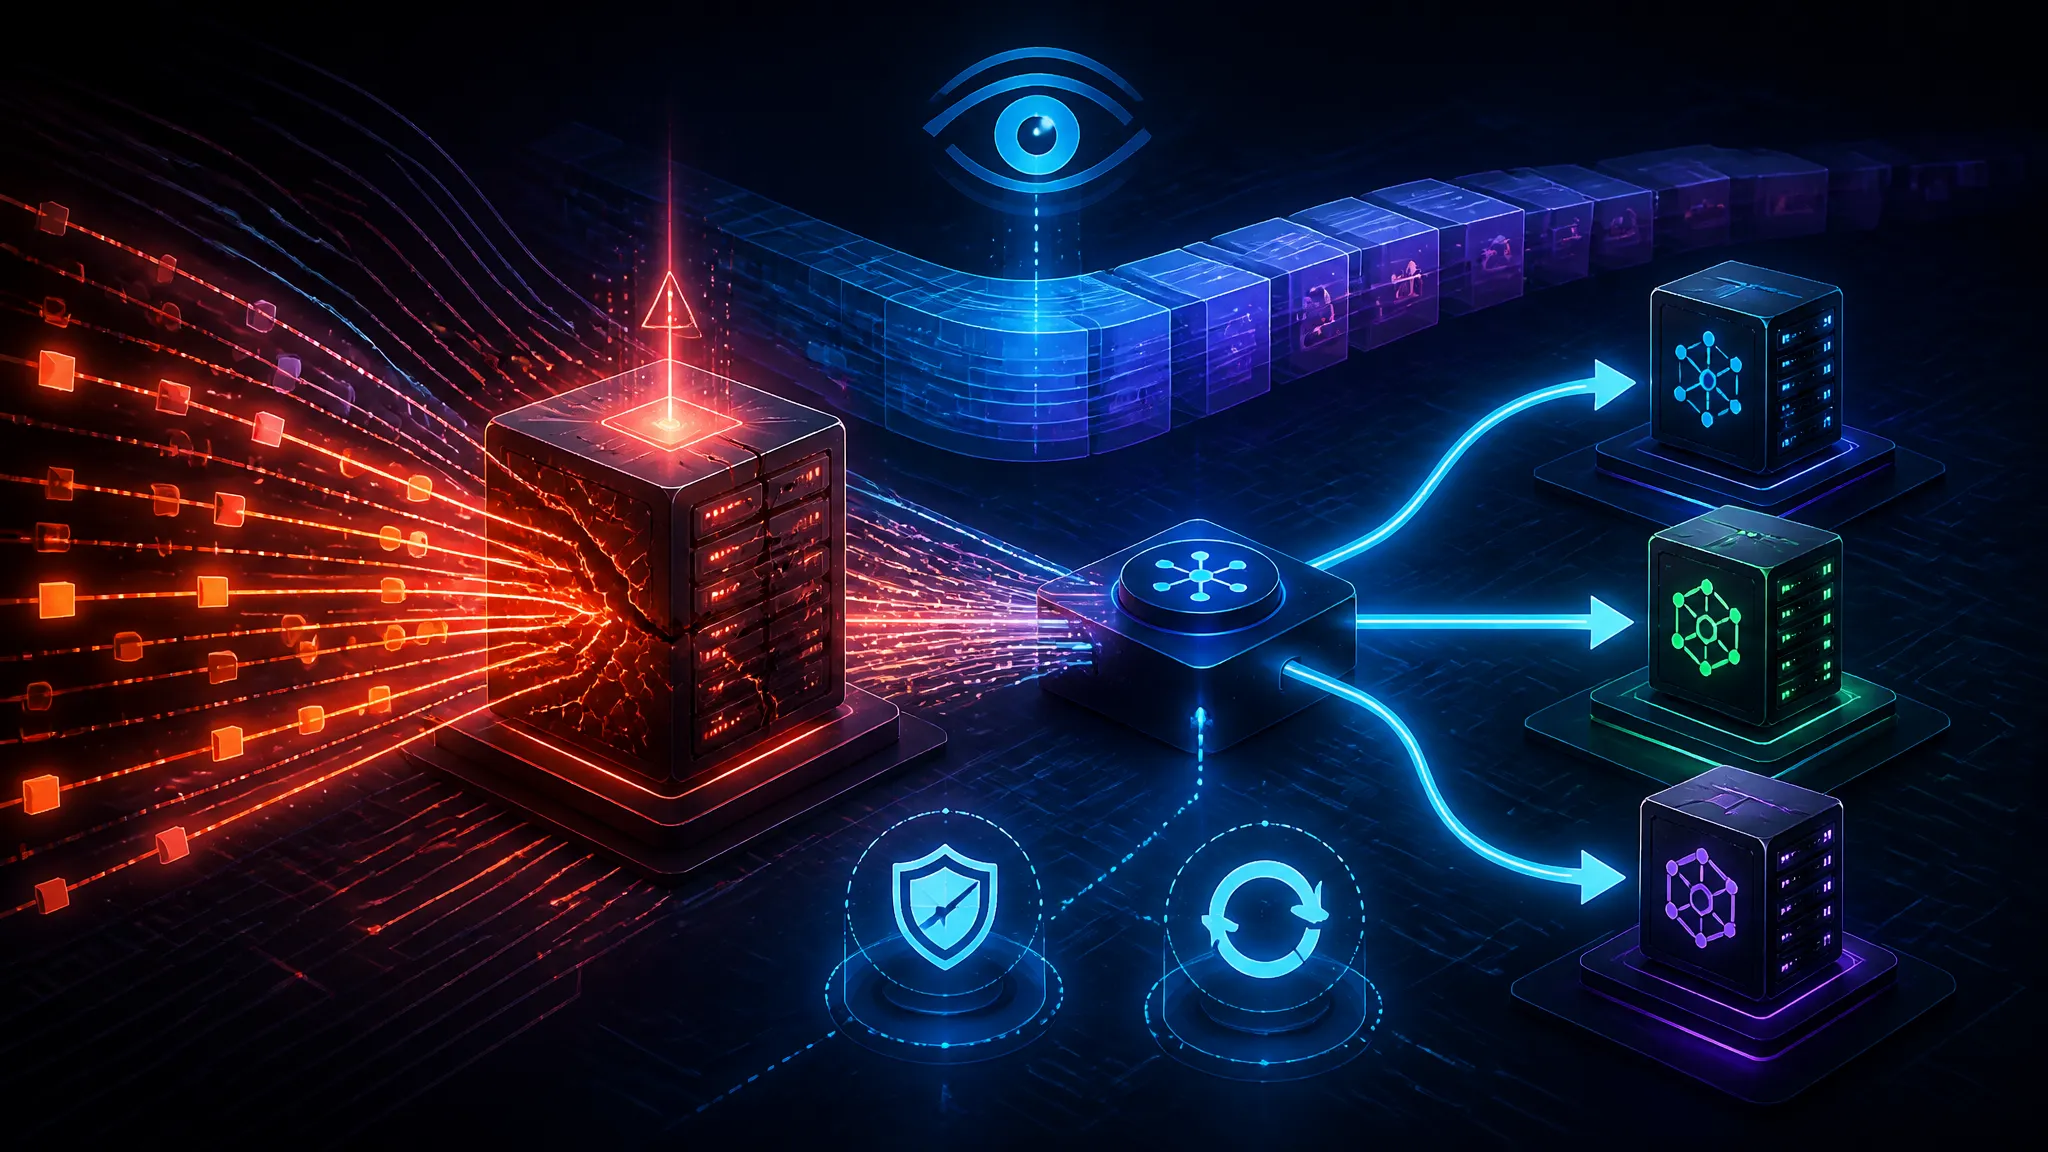
A wrapper swaps a base URL. A router owns policy: candidate selection, health, fallback order, deadlines, degradation tiers, telemetry. The core is smaller than people expect.
const providers = [
{ id: "primary",   endpoint: process.env.AI_PRIMARY_URL,   priority: 0,
  capabilities: ["chat", "tools", "json", "stream"], contextTokens: 128_000 },
{ id: "secondary", endpoint: process.env.AI_SECONDARY_URL, priority: 1,
  capabilities: ["chat", "tools", "json", "stream"], contextTokens: 128_000 },
{ id: "budget",    endpoint: process.env.AI_BUDGET_URL,    priority: 2,
  capabilities: ["chat", "json"], contextTokens: 32_000 },
];

export function candidates(need, health) {
return providers
  .filter((p) => need.caps.every((c) => p.capabilities.includes(c)))
  .filter((p) => p.contextTokens >= need.contextTokens)
  .filter((p) => health[p.id].circuit !== "open")
  .sort((a, b) =>
    health[b.id].score - health[a.id].score || a.priority - b.priority
  );
}
Capability Matching Across Providers
Don't route on model-name equality. Route on declared capabilities: tool calling, JSON mode, streaming, vision, context length, data residency. A request that needs tools must never silently land on a model without them, and a 60k-token prompt must never land on a 32k model. Encode it as data, and fail closed.
Health Scoring and Circuit Breaking
Score each provider over a sliding window, not a lifetime average, or a recovered provider never sees traffic again.
const WINDOW_MS = 60_000;
const OPEN_AFTER_FAILURES = 3;
const HALF_OPEN_AFTER_MS = 15_000;

export function score(samples) {
const now = Date.now();
const recent = samples.filter((s) => now - s.at < WINDOW_MS);
if (!recent.length) return 1; // unknown provider gets a chance
const successRate = recent.filter((s) => s.ok).length / recent.length;
const p95 = recent.map((s) => s.ms).sort((a, b) => a - b)[
  Math.floor(recent.length * 0.95)
];
const latencyScore = Math.min(1, 4000 / Math.max(400, p95));
return 0.7 * successRate + 0.3 * latencyScore;
}
Open the circuit after three consecutive routing-relevant failures, move it to half-open after 15 seconds, and let a single probe decide. Don't count 401s or schema violations toward the circuit. Those are your bugs, and tripping the breaker on them buries a config error behind a failover.
Fallback Ordering and Model Equivalence
Ordering is per capability class, not global — a JSON-only batch job and an interactive streaming chat want different fallbacks. Equivalence is the step teams skip: before promoting a fallback to production, run a golden set of prompts through both models and compare structured output validity, refusal behaviour, and tool-call shape. Models are not drop-in replacements, and a fallback that returns a different JSON shape is an outage you scheduled yourself.
Queueing and Idempotency Without Exactly-Once Fiction
Deadline-Aware Admission Control
Propagate a deadline from the user request and refuse work you can't finish. Queueing a request that will time out anyway just moves the failure later and burns capacity on the way.
export function admit(req, { p95FirstToken, maxBudget }) {
const remaining = req.deadline - Date.now();
if (remaining < p95FirstToken) return { admitted: false, tier: "cached" };
return { admitted: true, timeout: Math.min(remaining, maxBudget) };
}
Idempotency Keys for Retried Requests
Send an Idempotency-Key derived from your own request id (tenantId:requestId), and don't assume the provider deduplicates it. Most LLM APIs don't document exactly-once semantics, and I'm not aware of any that guarantee it. Practically: dedupe at your edge, key your own writes by the same id, and never retry a request whose first attempt could already have executed a tool with side effects.
Treat idempotency as your invariant. Provider-side dedupe, where it exists, is a bonus — not a contract to build on.
Graceful Degradation Tiers Your Users Can Actually See
Cheaper Model, Same Contract
Tier two is a smaller, cheaper model — but only if it satisfies the identical response schema. If downstream code branches on which model answered, you haven't degraded gracefully; you've shipped a second product path.
Cached, Retrieval-Only, and Explicit Refusal Modes
Tier three serves a cached or retrieval-only answer with a visible label: "this answer is from cache; live generation is degraded." Tier four is an honest refusal with a retry affordance, not an infinite spinner. Quietly substituting a weaker answer is a trust defect, and it's the failure users remember.
Observability and Failover Drills
Per-Provider SLIs and an Error Taxonomy
Track per provider: attempt count, success rate, error code distribution, time-to-first-token, total latency, tokens billed after a failed stream, and how often a request was served by a non-primary provider. That last one is the metric telling you whether your router does anything at all.
Fault Injection Before Production
You can't rehearse a provider's outage, but you can rehearse your response. Point the router at a local stub that fails on command:
node test/failover-drill.mjs --fail primary --mode abort-after-100-tokensattempt 1 provider=primary outcome=stream_truncated ttft=812ms tokens=100
attempt 2 provider=secondary outcome=ok ttft=640ms tokens=431
circuit primary=open(15s) consecutive_failures=1/3
degraded false
served_by secondary
Those numbers are illustrative output from the local stub, not measurements of any vendor. What matters is the assertion set: the truncated stream is detected, the retry budget is respected, circuit state is correct, and the response isn't marked degraded when a healthy fallback answered.
Cost, Credits, and What a Refund Does Not Cover
The DeepSeek report says users were refunded. That's a sensible operator response and worth noting, but credits are not a reliability control. They arrive after the incident, they cover the invoice rather than the impact, and they do nothing for the engineer on the bridge call or the user who abandoned the workflow. Your own failure cost — wasted retries, tokens billed on truncated streams, support load — is the number worth tracking.
What Is Confirmed and What Is Still Unknown
Confirmed by the reports, as of 15 October 2026: DeepSeek refunded users after a second outage within three days; most Yandex AI services were restored after an outage; Russia's tax service suffered a widespread disruption after reported drone attacks on data centers.
Unknown, and worth waiting for primary sources on: root causes, outage durations, affected regions and endpoints, whether refunds were automatic or requested, whether any incident shares infrastructure with another, and which SLA credits — if any — apply. A status page or postmortem turning up later would change the incident narrative but not the routing design.
Further Reading
- Russia's tax service suffers widespread outage after reported drone attacks on major data centers — The New Voice of Ukraine, 15 Oct 2026
- DeepSeek Refunds Users After Its Second Outage in Three Days — Trending on Weibo, 15 Oct 2026
- Most Yandex AI services restored after outage — www1.ru, 15 Oct 2026
- Handling Overload — Google SRE Book, on admission control and client-side throttling
- Exponential Backoff and Jitter — AWS Architecture Blog, on why full jitter beats fixed backoff