Where CUDA Assumptions Leak Into PyTorch CI/CD on AWS Trainium
Introduction
Amazon says it will open-source TorchNeuron so PyTorch models run on AWS Trainium "without a rewrite," according to coverage from 19–20 October 2026. This post explains where implicit CUDA assumptions leak into PyTorch CI/CD when you target Trainium, and which build, test, benchmark, and deployment changes make that migration survivable.
If you have ever ported a training stack to a second accelerator, your first reaction probably wasn't excitement — it was a mental list of the forty places in your pipeline where cuda is hardcoded.
That instinct is right. The model definition is the easy part. Around it sits the actual work: the build layer that compiles custom ops, the wheel index your Dockerfile pins, the test suite that silently skips instead of failing, the benchmark harness built on torch.cuda.Event, and the deploy config that autodetects a device at runtime and quietly falls back to CPU.
This post takes one position: "no rewrite" will hold at the model-definition layer and break at the edges. The teams that get value from Trainium will be the ones who already made the accelerator a parameter — not the ones who start after the announcement.
What the TorchNeuron Announcement Claims About PyTorch on AWS Trainium
What the announcement confirms
The public coverage I have—Amazon's announcement plus trade coverage from 19 and 20 October 2026—states a few things:
- TorchNeuron is an open-source bridge from Amazon.
- It lets PyTorch models run on AWS Trainium chips.
- Existing PyTorch models run "no rewrite needed."
- The framing across coverage is that this reduces Nvidia's software moat by making Trainium a mainstream PyTorch target.
That is as far as the public material goes at this level of detail. The report says these things; I have not verified them against a released repository or a compile run, because as far as the public material shows, this is an announcement.
What the TorchNeuron announcement leaves unconfirmed
At least as relayed in the coverage I have, the announcement does not state:
- Whether TorchNeuron replaces or wraps the existing Neuron SDK path (which, per prior AWS documentation going back several generations, involves XLA-based compilation and a
torch-neuronx-style package), and whether existing users migrate or run both. - Which PyTorch versions are supported at launch.
- How custom CUDA C++ extensions and Triton kernels — the actual source of most "rewrite" cost — are handled.
- What numerical parity looks like against a CUDA baseline for training, as opposed to inference.
- Whether distributed training across Trainium nodes is supported at launch, and through which collective backend.
Unconfirmed: the distributed and custom-kernel stories. If TorchNeuron only covers eager-mode inference on standard torch.nn modules, "no rewrite" is true for a demo and false for a production training stack. That distinction decides everything, and you should not plan a migration until you can read the answer in the source.
Where CUDA Assumptions Leak Into a PyTorch CI/CD Pipeline
Device strings, capability probes, and silent CPU fallback
The most dangerous pattern is the silent fallback:
device = "cuda" if torch.cuda.is_available() else "cpu"
On a Trainium instance, torch.cuda.is_available() returns False, and this line does not error — it hands you CPU. Your suite goes green. Your job takes 40× longer and nobody notices until the bill arrives. Search for torch.cuda.is_available, .cuda(), "cuda:0", torch.cuda.current_device(), and torch.cuda.synchronize() across the repo. Recent PyTorch 2.x releases have a torch.accelerator module that abstracts device selection, but its exact semantics move between minor versions, so verify against your pin rather than trusting a blog post — including this one.
Custom CUDA extensions and the missing nvcc toolchain
torch.utils.cpp_extension.CUDAExtension needs nvcc and CUDA_HOME. On Trainium that toolchain is absent. The good news: a missing compiler is a loud failure. The bad news is the guards people wrote around it:
if CUDA_HOME is not None:
    ext_modules = [CUDAExtension("fused_ops", ...)]
else:
    ext_modules = []  # "just skip it locally"
That branch turns a build failure into an ImportError at runtime, or worse, into a Python fallback path that is 100× slower and never benchmarked. Anything using Triton kernels, flash-attention variants, or hand-written fused ops should be treated as out of scope for "no rewrite" until proven otherwise. I expect the migration cost to concentrate there.
Wheel tags, index URLs, and pinned base images
A Dockerfile line like this is a backend commitment:
pip install torch --index-url https://download.pytorch.org/whl/cu124
That pulls a CUDA-linked build plus several gigabytes of runtime libraries, and it is the wrong artifact for a non-CUDA device. Wheel compatibility is governed by platform tags (PEP 425) and manylinux baselines (PEP 600) — so your lockfile needs a per-backend split, and your base image needs a digest pin, not :latest. One lockfile for two backends will resolve to something that satisfies neither.
Collectives, AMP, and determinism flags that assume CUDA
Three more leak points, all subtle:
init_process_group(backend="nccl")is CUDA-only. NCCL does not exist off Nvidia hardware. The correct backend name for the Neuron collective path has to come from the SDK docs — I am not going to guess it.torch.cuda.amp.autocast()should already betorch.autocast(device_type=device.type, dtype=torch.bfloat16); the CUDA-specific form is deprecated and, more importantly, pins the dtype policy to one backend.torch.use_deterministic_algorithms(True)andCUBLAS_WORKSPACE_CONFIGhave per-backend operator coverage. A config that passes on CUDA may raise on Trainium, or — worse — silently change which ops are allowed and shift your numerics.
Build Layer: Making PyTorch Artifacts Backend-Aware
Build two artifacts from one source, and tag both with the same git SHA:
registry/model:sha-9f2c1a-cu124
registry/model:sha-9f2c1a-trn
Same source, same tests, different base image and lockfile. Same SHA means the benchmark diff is attributable to the backend rather than to a commit. Record (git_sha, backend, torch_version, backend_sdk_version, python_version) into a build_manifest.json and bake it into the image. When someone asks "why is Trainium slower this week," that file answers half the question in ten seconds.
Test Layer: Turning Silent Accelerator Skips Into Failures
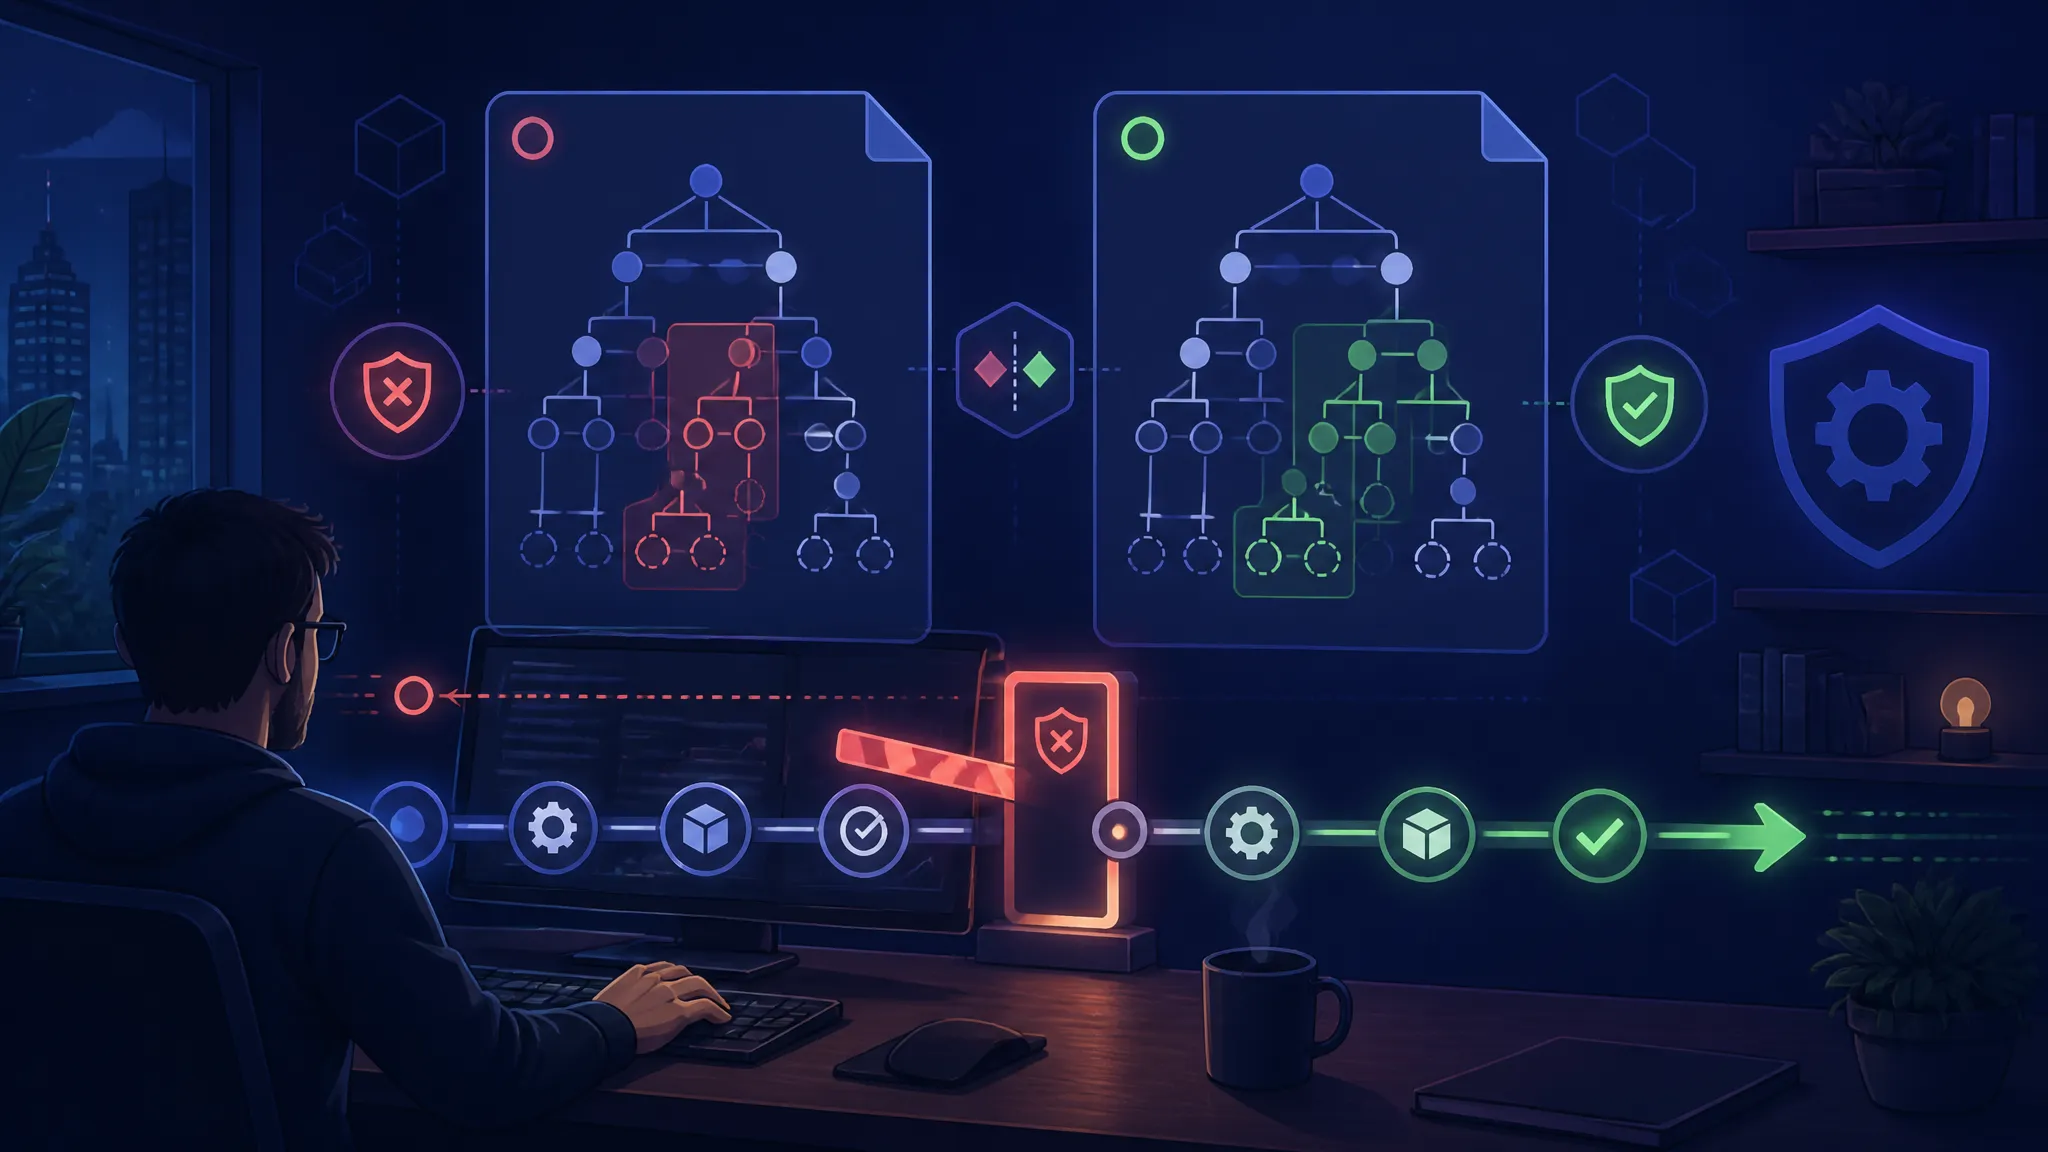
Enforce one rule: a skip is a bug unless the job declared it may skip.
Mark accelerator-dependent tests explicitly, then have the CI job declare what it must exercise:
REQUIRED_ACCELERATOR=neuron pytest -q --strict-markers -ra
If the job declares neuron and the accelerator is not present, the session must exit non-zero before collecting tests. A job that reports "412 passed, 88 skipped" on a backend-specific runner is a lie you are paying for.
Benchmark Layer: Baselines That Survive a Second Accelerator
Keep baselines keyed by (git_sha, backend, dtype, batch_size, compiler_version) as JSON, and gate only same-backend regression: current run vs. the rolling median of the last N runs on that same backend. Cross-backend latency is reported, never gated. Every cross-backend latency test I have seen goes flaky within a quarter, because compile caches, driver versions, and thermal/neighbour noise all move independently.
Watch for timing code built on torch.cuda.Event. It does not exist on a non-CUDA device; use time.perf_counter around a barrier appropriate to your backend (the torch.accelerator.synchronize()-style call), and warm up properly — compilation-backed runtimes need more warmup iterations than eager CUDA, not fewer.
Deploy Layer: Runtime Selection, Rollback, and Cost Controls
Two things matter here. First, make backend selection explicit config, not autodetection. ACCELERATOR=trn in the deployment manifest, validated at startup, failing closed. Autodetection is how you get a service quietly serving from CPU at a fraction of the throughput with no alarm.
Second, rollback must be a config change, not a rebuild. Keep the previous backend's image tagged and addressable. Treat compile-cache warmup as a cost line item too: compiler-backed runtimes pay a startup penalty, which interacts badly with aggressive autoscaling and spot reclamation. Warm the cache in the image or in a pre-scale hook, or your p99 startup will be a mystery.
A Device-Agnostic conftest.py Pattern That Fails Loudly
import importlib.util


## Declared by the CI job, not sniffed. Empty string means CPU-only is fine.
REQUIRED = os.environ.get("REQUIRED_ACCELERATOR", "")


def detect_accelerator() -> str:
  if torch.cuda.is_available():
      return "cuda"

  # Replace "torch_neuronx" with the module that TorchNeuron or the Neuron SDK
  # exposes. This name is the pre-announcement path and is UNVERIFIED for
  # TorchNeuron - check the released source before relying on it.
  if importlib.util.find_spec("torch_neuronx") is not None:
      return "neuron"

  return "cpu"


@pytest.fixture(scope="session", autouse=True)
def enforce_backend():
  detected = detect_accelerator()
  print(f"
[conftest] accelerator={detected} torch={torch.__version__}")

  if REQUIRED and detected != REQUIRED:
      # Exit code 2 = configuration error, not a test failure.
      pytest.exit(
          f"job requires accelerator={REQUIRED!r} but detected {detected!r}",
          returncode=2,
      )
  yield detected


@pytest.fixture(scope="session")
def device(enforce_backend):
  if enforce_backend == "cuda":
      return torch.device("cuda")
  if enforce_backend == "neuron":
      # Map to the torch.device your backend actually exposes.
      return torch.device("cpu")  # PLACEHOLDER - resolve from SDK docs
  return torch.device("cpu")
The behaviour that matters is exit code 2. A misconfigured accelerator is not a test failure someone retries; it is a broken pipeline that should block the merge. Illustrative output from the probe on a CPU-only runner (not measured on Trainium):
[conftest] accelerator=cpu torch=2.6.0
!!! job requires accelerator='neuron' but detected 'cpu'
Exit: configuration error (code 2)
Guarding Numerical Parity Without Building a Flaky Suite
Use torch.testing.assert_close against frozen reference tensors, generated once on a declared backend and committed — not recomputed on each run. Recomputing the reference on the new backend only tests that the backend agrees with itself.
The tolerances below are starting points for discussion, not measurements — I have not run them against Trainium:
| dtype | rtol | atol | Notes |
|---|---|---|---|
| fp32 | 1e-5 | 1e-7 | tightest; expect some op-level exceptions |
| fp16 | 1e-3 | 1e-5 | reduce ops accumulate error |
| bf16 | 1e-2 | 1e-3 | training-forward sanity only |
Two guardrails: check a bounded golden set of ops and short layers rather than whole-model logits, and assert top-1 class stability on a fixed input batch rather than exact scores. Whole-model tensor equality across accelerators is a test that fails for reasons nobody can debug at 2 a.m.
Migration Checklist for Teams Adding AWS Trainium
- Audit for
torch.cuda.*,.cuda(),"cuda:N",nccl,CUBLAS_WORKSPACE_CONFIG. - Split lockfiles per backend; pin base images by digest.
- Build two artifacts, one git SHA, both published.
- Replace silent
is_available()fallbacks with declared, validated config. - Convert accelerator-dependent skips into exit-code-2 configuration errors.
- Port timing code off
torch.cuda.Event. - Freeze reference tensors; separate parity tests from regression tests.
- Gate same-backend regressions only; report cross-backend as data.
- Make deploy backend selection a manifest field with a documented rollback.
Where I Would Place My Bet on TorchNeuron Migration
Model code will port. Pipeline glue will not, and it will cost more than the model code ever did.
The reason is structural: PyTorch operators are a defined surface, and a bridge that lowers them is a bounded engineering problem. Your pipeline is not a defined surface. It is an accretion of if cuda branches, index URLs, timing harnesses, and one fused kernel somebody wrote in 2022 and nobody has touched since. "No rewrite" addresses the first and ignores the second.
So the concrete recommendation: spend this announcement cycle on inventory, not commitment. Grep your repos, count your skip markers, find your custom kernels, and make the accelerator a parameter. Do that, and a Trainium decision later is a config change plus a benchmark run. Skip it, and you will meet the same forty leak points under deadline pressure — exactly the situation the "no rewrite" framing encourages you to walk into.
The one diligence task worth doing yourself: read the TorchNeuron source. It is being released as open source. The supported-op list, the compile pipeline, and the distributed backend coverage are all in there, and they answer every "unconfirmed" item above in a way no press release can.
Further Reading
- Amazon's own announcement post, "Amazon opens its AWS Trainium AI chips to every PyTorch developer, no rewrite needed" (19 October 2026) — as supplied via Google News aggregation
- Trade coverage: "Amazon unveils TorchNeuron to make its Trainium AI chips easier to use", Crypto Briefing, 19 October 2026
- AWS Neuron SDK documentation — the existing PyTorch-on-Trainium path; the distributed backend names and supported-op notes you will need
- PyTorch: CUDA semantics — the API surface to inventory against
- PyTorch:
torch.amp— device-agnostic autocast - PyTorch: Reproducibility — deterministic algorithm flags and their backend caveats
- PEP 425 — Compatibility tags for built distributions, PEP 600 — manylinux platform tags — why your wheel index is a backend commitment