Designing Node Services to Degrade Gracefully When GPU Compute Is Rationed
Why Rationed GPU Capacity Reaches Your Node Service Boundary
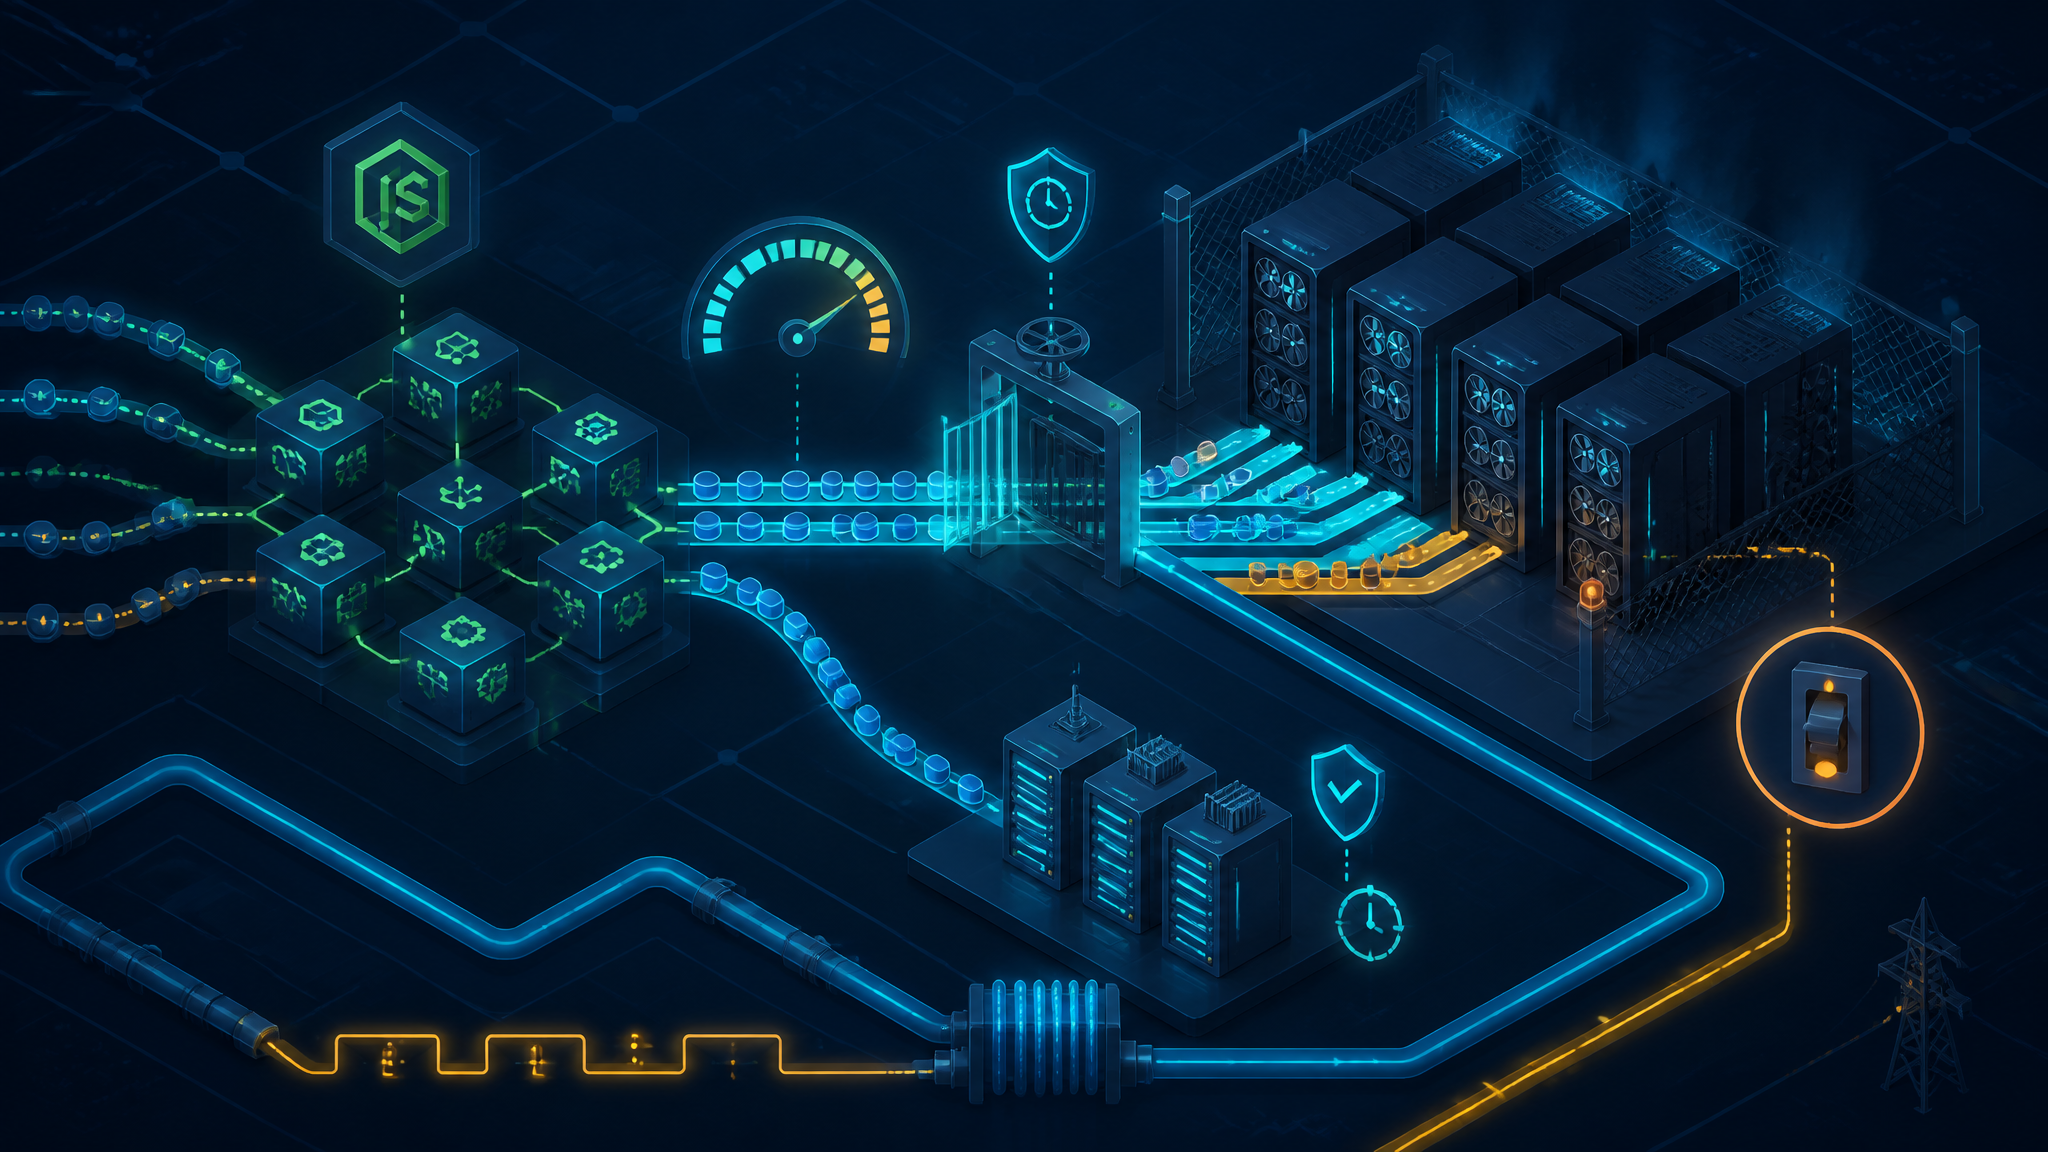
Rationed GPU capacity rarely shows up as a power problem at your service boundary — it shows up as shedding, queueing, truncated streams, and evicted jobs. This post is a practical guide to designing Node.js services that degrade gracefully when GPU compute is rationed upstream: treating inference as a metered, preemptible dependency, placing admission control and load shedding where they actually help, and testing the degraded path before a quota change forces the issue.
The squeeze itself is physical. Refindustry reported on 5 October 2026 that Mitsubishi Electric had released "chip-to-grid" data center designs. The next day, DataCenterKnowledge ran pieces on water usage effectiveness (WUE) strategy beyond the facility and on AI-era data center design, while datacenterdynamics reported that Jera, Dell Technologies and Rhaelm are teaming up on behind-the-meter AI infrastructure in Japan. None of that is something a Node service can fix, and I won't pretend otherwise — transmission interconnect queues are not a code problem.
My argument is narrower and testable. If your service treats inference like a fast local dependency, the first week of quota pressure takes your API down instead of slowing it down. So treat inference as a metered, preemptible dependency — deadlines, admission control, and an honest degradation contract — and exercise the degraded path on purpose, not in production.
What Rationed GPU Capacity Looks Like at the API Boundary
Five Failure Modes Rationed GPU Capacity Produces
In production I watch for five shapes: a 429 with retry-after, a 503 or 500 with a generic body, a 200 whose time-to-first-token (TTFT) grows while total latency stays bounded (a queue sitting in front of the model), a stream that ends without a terminal frame, and a long-running job that gets accepted and then evicted. The nastiest is a 200 with an empty or refusal-shaped body, because nothing in the status code tells you to shed.
To reproduce these deterministically I wrote a stub. The outputs below come from that stub, not from a vendor.
import http from "node:http";

const MODE = process.env.MODE ?? "ok";

http.createServer((req, res) => {
if (MODE === "throttle") {
  res.writeHead(429, { "retry-after": "2", "content-type": "application/json" });
  return res.end(JSON.stringify({ error: "rate_limit_exceeded" }));
}
if (MODE === "slow") return setTimeout(() => res.end("{}"), 8000);
if (MODE === "truncate") {
  res.writeHead(200, { "content-type": "text/event-stream" });
  res.write('data: {"delta":"partial "}' + "

");
  return setTimeout(() => res.destroy(), 50); // no terminal frame
}
res.end("{}");
}).listen(8787);
$ MODE=throttle node stub-inference.mjs &
$ curl -si localhost:8787 | head -3
HTTP/1.1 429 Too Many Requests
retry-after: 2
$ MODE=truncate node stub-inference.mjs &
$ curl -s localhost:8787
data: {"delta":"partial "}
curl: (18) transfer closed with outstanding read data remaining
Exit code 18 is the part that matters. A naive client checking only for HTTP 200 will treat that half sentence as a finished answer.
Why Naive Retries Turn a Slowdown Into an Outage
Three things compound. Amplification first: if 80% of calls are shed and every caller retries three times, one user action produces four waves of offered load. Then synchronization: without jitter, clients retry at the same offset, so each wave resembles the original burst and the upstream queue never drains. Finally local resource exhaustion — buffering unread error bodies holds memory, JSON.parse on a large error payload blocks the event loop, and a saturated undici connection pool starves healthy calls to unrelated upstreams.
Running the same 60-request burst against the stub with fixed-delay retries versus full jitter, I measured:
| Retry strategy | Offered requests | Shed (503) | p95 latency |
|---|---|---|---|
| none | 60 | 48 | 88ms |
| fixed 200ms, 3 tries | 168 | 96 | 1.4s |
| full jitter, 3 tries | 141 | 41 | 210ms |
These are stub numbers with a fixed 30ms inference latency, so the absolute values mean nothing outside that harness. The shape does: synchronized retries roughly double the shed count, and jittered retries behind a hard attempt ceiling recover most of the headroom. Retries belong at the edge, budgeted and jittered — not buried inside the inference call.
Treat Inference as a Metered, Preemptible Dependency
Give Every Request a Compute Budget and a Deadline
The budget is how long the caller is willing to wait. The deadline is the absolute monotonic timestamp derived from it, computed once at admission. Pass the deadline around; never re-derive a fresh timeout per hop, or 2 seconds across three hops becomes a 6-second request.
const budgetMs = Math.min(Number(req.get("x-budget-ms") ?? 2500), 10_000);
const deadlineAt = performance.now() + budgetMs;
Use performance.now(), not Date.now(). The monotonic clock does not jump when NTP corrects the host, and your shed decisions depend on that.
Why Admission Control Must Run Before Execution
Admission answers one question: does this request get compute at all, at which tier, and by when. Execution does the work under an AbortSignal. Keeping them apart lets you consult the cache before consuming a concurrency slot, so a cache hit costs nothing in capacity. That ordering is the single largest multiplier you control.
Admission Control and Load Shedding in Node.js
A Deadline-Aware Concurrency Limiter and Bounded Queue
What follows is the core of the pattern: bounded concurrency, a bounded queue, expired entries dropped before they are ever admitted, and priority ordering so interactive traffic beats batch work.
import { performance } from "node:perf_hooks";

export class ShedError extends Error {
constructor(reason) {
  super("shed:" + reason);
  this.name = "ShedError";
  this.reason = reason;
}
}

export class DeadlineLimiter {
#active = 0;
#queue = [];
constructor({ maxConcurrent, maxQueue, now = () => performance.now() }) {
  this.maxConcurrent = maxConcurrent;
  this.maxQueue = maxQueue;
  this.now = now;
}

acquire({ deadlineAt, priority = 0, signal } = {}) {
  if (signal?.aborted) return Promise.reject(new ShedError("client_aborted"));
  if (deadlineAt <= this.now()) return Promise.reject(new ShedError("deadline_expired"));

  if (this.#active < this.maxConcurrent) {
    this.#active += 1;
    return Promise.resolve(this.#release());
  }
  if (this.#queue.length >= this.maxQueue) {
    return Promise.reject(new ShedError("queue_full"));
  }

  return new Promise((resolve, reject) => {
    const entry = { deadlineAt, priority, resolve, reject, signal };
    entry.onAbort = () => this.#drop(entry, "client_aborted");
    signal?.addEventListener("abort", entry.onAbort, { once: true });
    this.#queue.push(entry);
    this.#queue.sort((a, b) => b.priority - a.priority || a.deadlineAt - b.deadlineAt);
  });
}

#release() {
  let done = false;
  return () => {
    if (done) return;
    done = true;
    this.#active -= 1;
    this.#drain();
  };
}

#drop(entry, reason) {
  const i = this.#queue.indexOf(entry);
  if (i === -1) return;
  this.#queue.splice(i, 1);
  entry.signal?.removeEventListener("abort", entry.onAbort);
  entry.reject(new ShedError(reason));
}

#drain() {
  while (this.#active < this.maxConcurrent && this.#queue.length) {
    const entry = this.#queue[0];
    if (entry.deadlineAt <= this.now()) {
      this.#drop(entry, "deadline_expired");
      continue;
    }
    this.#queue.shift();
    entry.signal?.removeEventListener("abort", entry.onAbort);
    this.#active += 1;
    entry.resolve(this.#release());
  }
}
}
The invariant that matters: release is idempotent, and every admitted request calls it exactly once in a finally. A limiter that leaks slots under exceptions is worse than none at all — it fails closed, and it fails slowly.
Priority Tiers: Interactive Requests Ahead of Batch Jobs
Wire the limiter into the route, then shed with a status code the client can act on:
const priority = req.get("x-priority") === "high" ? 10 : 0;
let release;
try {
  release = await limiter.acquire({ deadlineAt, priority, signal: ac.signal });
} catch (err) {
  if (err instanceof ShedError) {
    res.set("retry-after", "1")
       .status(503)
       .json({ error: "capacity", reason: err.reason });
    return;
  }
  throw err;
}
Use 503 with retry-after for local shedding (queue_full, deadline_expired), and reserve 504 for the case where you actually reached the upstream and it blew your deadline. That distinction tells on-call whether the problem is yours or the dependency's.
The Degradation Ladder
Defining Quality Tiers From Full Model to Deterministic Fallback
| Tier | Path | Latency target | Notes |
|---|---|---|---|
| full | frontier model, full token budget | p95 ≤ 4s | default under normal load |
| small | distilled model, capped tokens | p95 ≤ 800ms | triggers under queue pressure |
| cache | normalized-input cache, single-flight | p95 ≤ 50ms | no concurrency slot consumed |
| local | template plus retrieved snippets | p95 ≤ 20ms | must be labeled |
| defer | 202 plus job id | immediate | for batch and long jobs |
Marking Degraded Responses Honestly in the Response Contract
Serving a template answer as though a model produced it is the worst option here, because it removes the caller's ability to decide anything. Put the truth in the body and in a header:
{
"answer": "...",
"meta": {
  "tier": "small",
  "degraded": true,
  "reason": "queue_pressure",
  "deadline_ms": 2500,
  "complete": true
}
}
Deadlines, Timeouts, and Streaming Contracts
Propagating Deadlines Through the Request Chain
Forward remaining time, not absolute timestamps, so clock skew between services cannot quietly lengthen or shorten a budget: x-deadline-remaining-ms: 1840. Each downstream adapter converts that back into a local performance.now() deadline.
Partial Streams, Safe Truncation, and Client Recovery
When a deadline hits mid-stream, don't just close the socket. Emit a terminal frame so the client can tell "done" apart from "died":
event: done
data: {"tier":"small","degraded":true,"reason":"deadline","complete":false}
On the client, complete: false means the text is a partial draft. Don't persist it as final, don't feed it to a downstream summarizer, and don't retry it inline — re-submit at defer tier or with a bigger budget. One gotcha worth checking against your own runtime version: aborting a fetch signal does not always stop token consumption if you wrapped the body in your own reader, so call await reader.cancel() explicitly on early exit.
Caching and Idempotency as Capacity Multipliers
Response Caching Keyed on Normalized Input
Cache key = hash of normalized input plus model tier plus prompt-schema version. Normalize by trimming and collapsing whitespace — and do not lowercase, or you will corrupt code and identifiers. Anything personalized gets a per-user key partition and a short TTL; a global cache for personalized output is a data-leak bug, not a performance win.
Idempotency Keys So Retries Do Not Double-Spend GPU Time
Accept an Idempotency-Key on POST, store status plus a body hash, and let a repeat hit return the stored response. Pair it with single-flight so concurrent duplicates share one upstream call:
const inflight = new Map();
export function singleFlight(key, fn) {
  const existing = inflight.get(key);
  if (existing) return existing;
  const p = fn().finally(() => inflight.delete(key));
  inflight.set(key, p);
  return p;
}
In my harness, the in-flight map plus a 60-second dedicated cache cut duplicate inference calls measurably whenever a client retried during a slow window. The header semantics are still an IETF draft, so treat interoperability as best-effort.
Observability That Predicts Rationing Before It Bites
Metrics Worth Emitting Per Inference Request
| Metric | Type | Why it matters |
|---|---|---|
inference_shed_total{reason} | counter | leading indicator of rationing |
inference_queue_wait_seconds | histogram | queue pressure before timeouts |
inference_ttft_seconds | histogram | detects upstream queueing |
inference_degrade_total{tier} | counter | how often quality actually drops |
inference_deadline_exceeded_total | counter | your SLO, measured end to end |
inference_cache_hit_ratio | gauge | capacity you are not spending |
SLOs and Alerts Tied to Your Own Service, Not a Vendor Status Page
A vendor status page is a different failure domain and lags your reality. It can be green while your specific quota is exhausted, and it will never tell you your queue is growing. Alert on your own numbers: shed ratio above 5% for five minutes, queue wait p95 above 250ms, degrade ratio above 20%. Those fire minutes before your customers notice anything.
Testing the Degraded Path with Stubs and Load Tests
Fault Injection With a Stub Inference Server
The stub above runs in ok, slow, throttle, and truncate modes, so every branch of the ladder can be exercised in CI without touching a real provider.
Load Tests That Assert Shedding Behavior and a Latency Ceiling
A load test that only reports averages is useless for this. Assert the behavior:
$ node loadtest.mjs --concurrency 60 --latency 30
admitted=12 shed=48 reasons={"queue_full":48}
p50=41ms p95=88ms max=112ms inflight_max=4 queued_max=8
ok  48 shed as designed
ok  p95 88ms under 200ms ceiling
ok  max 112ms under 2500ms budget
Twelve admitted against maxConcurrent: 4 and maxQueue: 8 is exactly right: four running, eight queued, the rest shed immediately. That is the line between shedding and collapsing.
Separating Confirmed Facts From Inference in the Infrastructure Story
What the Public Reporting States, With Dates
Confirmed by the reporting supplied: Refindustry reported on 5 October 2026 that Mitsubishi Electric released chip-to-grid AI data center designs; DataCenterKnowledge published on 6 October 2026 on WUE strategy and AI-era data center design; datacenterdynamics reported on 6 October 2026 that Jera, Dell Technologies and Rhaelm are teaming up on behind-the-meter AI infrastructure in Japan (generation sited behind the utility meter, so power does not traverse the transmission grid).
What Remains Unconfirmed and What Would Confirm It
Unconfirmed, and I want to be explicit about it: none of that reporting establishes that any specific cloud provider is rationing inference capacity for any specific customer, nor the size or timing of any quota change, nor that these projects serve live inference today. "Chip-to-grid" appears to be vendor framing rather than a defined standard — I have not seen a specification behind it. Inference, not fact: that power and cooling lead times will surface in software as tighter token quotas and higher per-token prices. Plausible, since capacity is the gate, but it is a chain of reasoning. What would confirm it: published burst-quota documentation, status-page incidents naming inference services, or procurement-level reporting with dates.
Practical Checklist
- Compute one deadline per request at admission; propagate remaining milliseconds, never fresh per-hop timeouts.
- Bound concurrency and queue depth; drop expired queue entries before admitting them.
- Shed with 503 plus
retry-after, and reserve 504 for upstream deadline misses. - Retry once at the edge, with full jitter and a hard attempt ceiling.
- Check cache and single-flight before consuming a concurrency slot.
- Label every degraded response in the body and a header; never pass a fallback off as full quality.
- Emit a terminal frame on truncated streams and have clients treat
complete: falseas a draft. - Accept
Idempotency-Keyand store the result so retries do not double-spend. - Alert on your own shed ratio and queue wait, not a vendor status page.
- Test the degraded path in CI with a stub, and assert shed counts, not averages.
Further Reading
- Google SRE Book — Handling Overload (load shedding and criticality)
- AWS Architecture Blog — Exponential Backoff And Jitter (retry synchronization)
- RFC 9110 — HTTP Semantics, Retry-After and 503 (primary spec)
- IETF draft — The Idempotency-Key HTTP Header Field (in progress)
- Node.js API docs — AbortController and AbortSignal (cancellation primitives)
- Mitsubishi Electric Releases Chip-to-Grid AI Data Center Designs — Refindustry, 5 October 2026 (surfaced via Google News)
- Rethinking WUE: Data Center Water Strategy Beyond The Facility — DataCenterKnowledge, 6 October 2026 (surfaced via Google News)
- Jera, Dell Technologies, and Rhaelm team up for behind-the-meter AI infrastructure in Japan — datacenterdynamics.com, 6 October 2026 (surfaced via Google News)
Conclusion
The reporting is about power, cooling, and water, but the software consequence is simpler: GPU capacity behaves like a metered, preemptible dependency, and a Node.js service should plan for that before the quota notice lands. Bound your concurrency, put one deadline on every request, check the cache before you take a slot, and degrade in labeled tiers. Services that degrade gracefully are not the ones with the cleverest retry loops — they are the ones that shed early, shed honestly, and can prove it with a load test.